Synthetic data has a trust problem, not just a quality problem
Generated data can expand testing and training, but its value depends on whether teams can explain what it represents, what it leaves out and how it was validated.
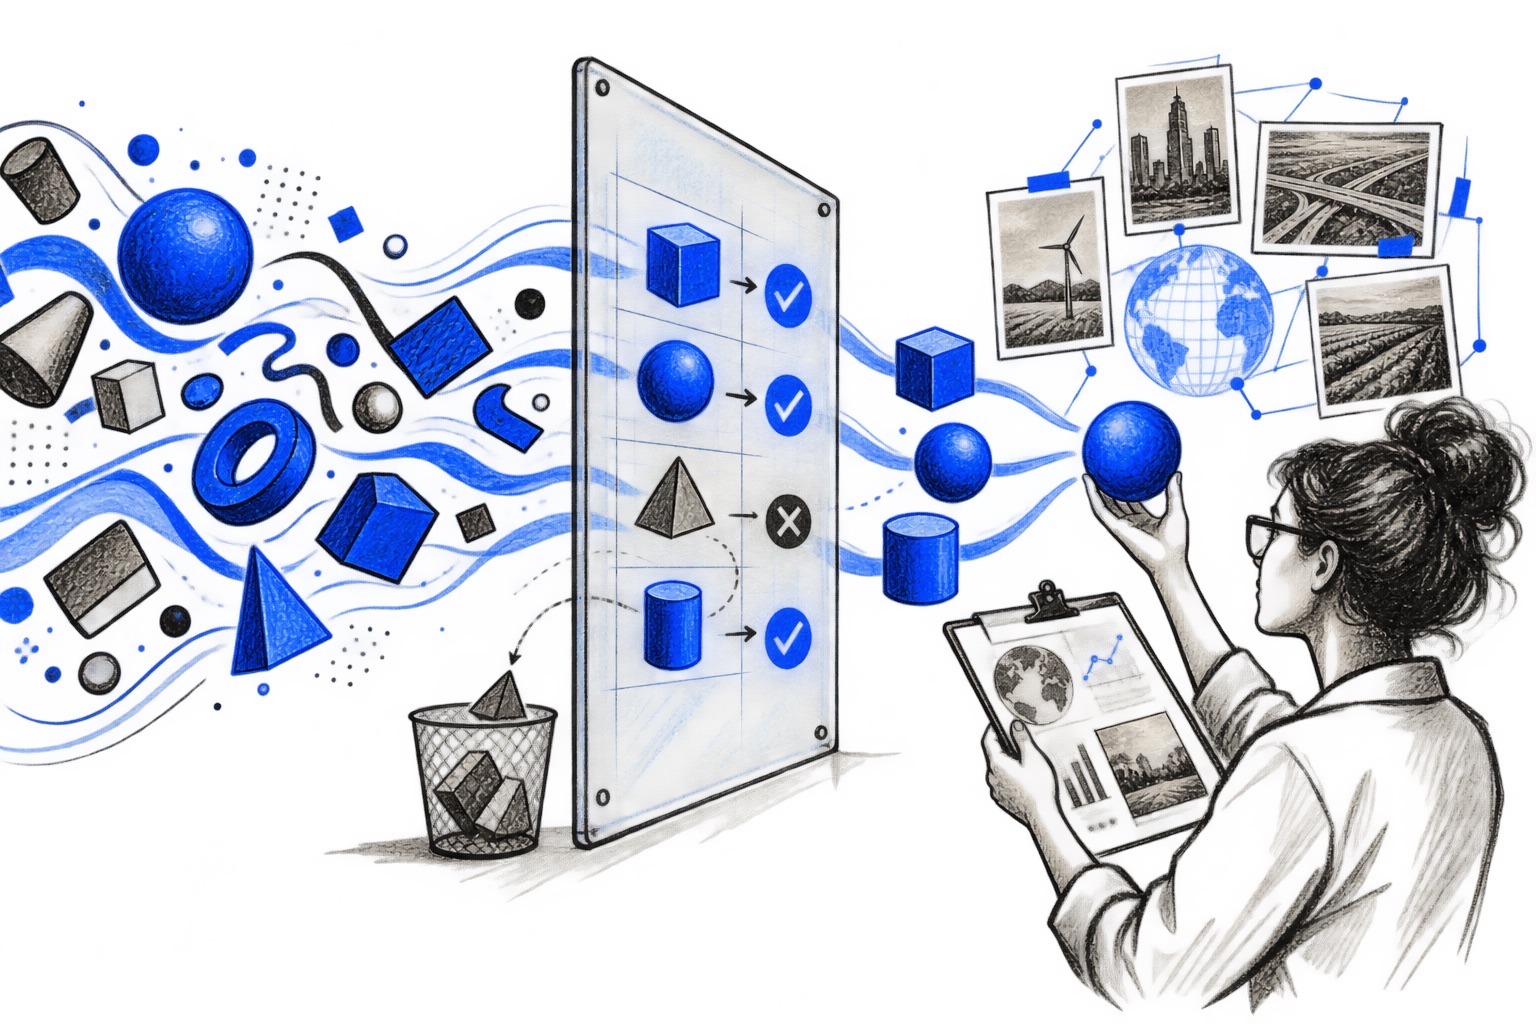
Synthetic data is appealing because real data is often scarce, sensitive or expensive to label. A generated dataset can help a team test a system, create rare scenarios or build an early prototype without exposing private records. Those are meaningful benefits, but they do not remove the need to understand what the data actually stands for.
The central question is trust. A team needs to know whether the synthetic examples preserve the patterns that matter for its decision, where they distort reality and whether a model trained or tested on them will behave safely once it meets a real user.
A realistic-looking record can still be misleading
Synthetic data can look plausible while missing the distribution, edge cases or correlations that make a real-world process difficult. A customer service dataset may contain believable conversations but fail to represent the complaints that trigger serious escalation. A medical or financial example may preserve form while losing the context that determines risk.
That is why visual plausibility is a poor test. Teams need explicit questions about what the dataset is intended to represent and which decisions it will support. The standard should be tied to the use case, not to whether a sample looks convincingly human to someone who has not defined the relevant behavior.
Provenance determines whether people can rely on it
A trustworthy synthetic dataset should carry a record of how it was created, what source material informed it, which transformations were applied and which limitations remain. This is not paperwork for its own sake. It gives downstream users a way to decide whether the data is appropriate for a new purpose or whether it should remain confined to a narrow test.
Provenance also helps when an issue appears later. A team can trace a failure back to a generation method, a missing category or an assumption that was never tested. Without that record, synthetic data can become a convenient but opaque input that nobody feels able to question.
Validation has to return to the real world
Synthetic data is most useful when it complements, rather than replaces, carefully governed real-world validation. A team can use it to create volume, stress scenarios and early coverage. It should still test the product against appropriate real examples before making claims about performance in a live environment.
This is especially important in high-stakes applications. The more a product affects access, safety or material outcomes, the less acceptable it is to assume that a synthetic representation captures the full complexity of the people and conditions involved. The final test remains whether the system works responsibly where it will be used.
Synthetic data is useful when its limits are visible
Generated examples can accelerate development and make sensitive work easier to test. They become reliable only when teams document their origin, validate their purpose and return to real-world evidence before the product earns trust.